Artificial Intelligence & Machine Learning
EchoTwin – AI-Powered Voice Digital Twin for Online Meetings
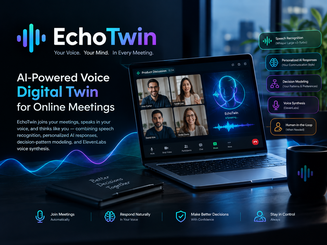
EchoTwin is an AI-powered voice digital twin designed to participate in online meetings on behalf of a user. It combines speech recognition, personalized AI responses, decision-pattern modeling, and ElevenLabs voice synthesis to replicate the user's communication style while escalating unfamiliar decisions to the actual user.
The challenge
Professionals frequently miss important online meetings due to scheduling conflicts, resulting in delayed decisions, repeated discussions, and communication gaps. Traditional AI meeting assistants primarily focus on transcription, summarization, and action-item extraction rather than actively representing an individual's communication style and decision-making patterns.
The challenge was to develop an AI-powered digital twin capable of understanding meeting conversations, generating personalized responses, and communicating through an enrolled voice profile. The system also needed to recognize situations where it lacked sufficient information and avoid making unsupported decisions on behalf of the user.
Context
EchoTwin was developed as a Final Year Project to explore how artificial intelligence, speech processing, and personalized decision modeling can improve online meeting participation.
The project focuses on two software development domains: Web Development and Artificial Intelligence/Machine Learning (AI/ML) Development. These domains provide a defined scope for learning user preferences, retrieving relevant historical context, and generating responses that reflect established communication and decision-making patterns.
The system uses a browser extension for meeting interaction, a React.js frontend, and a FastAPI backend. User onboarding includes consent, voice enrollment, and the collection of relevant historical information, such as previous conversations, meeting details, preferences, and decision history.
The solution
EchoTwin combines speech recognition, contextual AI processing, personalized response generation, and voice synthesis into a unified meeting-assistance workflow.
Meeting audio is converted into text using Whisper Large-v3-Turbo. The resulting transcription is combined with relevant meeting context and stored user history before being processed by the persona and decision model.
When sufficient information is available, EchoTwin generates a response designed to reflect the user's communication style, preferences, and decision-making patterns. ElevenLabs is used for text-to-speech and enrolled-voice output.
A confidence-based escalation mechanism supports human oversight. When relevant context is insufficient, the system notifies the actual user and defers the response instead of fabricating a decision. Verified responses and their relevant context can then be stored to improve future personalization.
Design
The design prioritizes a clear onboarding experience, understandable AI interactions, and effective human oversight.
The React.js interface supports user onboarding, consent, voice enrollment, historical data collection, personalization settings, and meeting-related notifications. The browser extension serves as the primary interaction layer between EchoTwin and supported online meeting environments.
The interaction flow separates automated responses from situations requiring human intervention. Users are notified when the system needs additional information, helping maintain transparency and control over important decisions.
The visual direction should communicate a professional AI product through clean layouts, accessible typography, subtle waveform visualizations, and a modern meeting-focused interface.
Architecture
EchoTwin follows a modular architecture consisting of a frontend, browser extension, backend API, AI processing pipeline, and data storage layer.
- Frontend: React.js for onboarding, personalization, notifications, and user interaction.
- Meeting integration: Browser extension for receiving meeting input and delivering generated responses.
- Backend: FastAPI for coordinating requests and connecting application components.
- Speech recognition: Whisper Large-v3-Turbo for converting meeting audio into text.
- Persona and decision model: PyTorch, Hugging Face Transformers, and PEFT/LoRA for model development and personalization.
- Voice synthesis: ElevenLabs for generating speech using the enrolled voice profile.
- Database: PostgreSQL for structured application data, meeting information, and personalization records.
- Context and learning: Retrieval of relevant user history, confidence-based escalation, and storage of verified human responses.
The pipeline follows this sequence: meeting audio → transcription → context retrieval → personalized response generation or human escalation → ElevenLabs speech synthesis → meeting response → history update.
Development
The development process covers requirements analysis, system architecture, AI pipeline implementation, frontend development, backend integration, and system testing.
The speech-processing pipeline uses Whisper Large-v3-Turbo to transcribe meeting conversations. The persona and decision model uses historical user information and relevant domain context to generate personalized responses. PyTorch, Hugging Face Transformers, and PEFT/LoRA support the model-development and personalization workflow.
The FastAPI backend coordinates the processing pipeline, while the React.js frontend and browser extension provide user-facing functionality and meeting integration. ElevenLabs is integrated for voice synthesis, connecting generated response text with spoken output.
Human-in-the-loop functionality is incorporated to handle unfamiliar situations safely. Testing focuses on transcription quality, response consistency, voice output, escalation behavior, and the use of verified responses for future personalization.
Results
EchoTwin is designed to demonstrate how a personalized AI digital twin can move beyond passive meeting transcription toward active, voice-based participation.
The intended outcomes include:
- A Whisper-based meeting transcription pipeline.
- Personalized response generation for Web Development and AI/ML Development discussions.
- Context retrieval using user history, preferences, and previous decisions.
- ElevenLabs-based voice output using an enrolled voice profile.
- A browser extension integrated with a React.js frontend and FastAPI backend.
- Human-in-the-loop escalation when relevant information is insufficient.
- History updates that support improved future personalization.
The project will be evaluated on speech recognition, consistency with the user's communication and decision-making patterns, voice output, and appropriate escalation to the actual user. Quantitative performance claims will be added after testing.